Output tokens are what the model generates — each one costs 2-8× more than input because the model predicts them sequentially. A million output tokens is thousands of responses accumulated over many API calls.
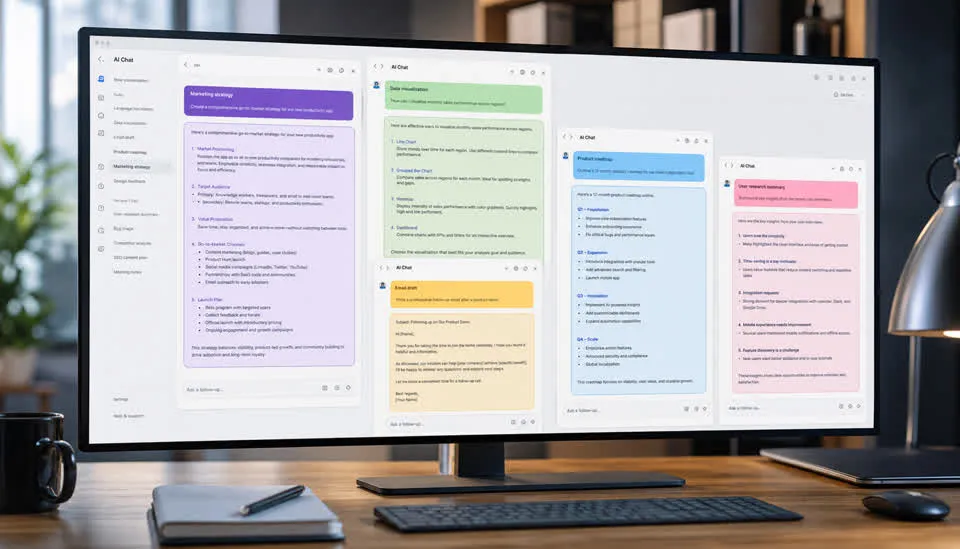
1 block = 1 response
💬≈ 2,000 detailed responses
long AI responses
A detailed AI response (explanation, analysis, essay) averages about 500 tokens. A million output tokens is roughly 2,000 of these — months of heavy daily usage.
basis: ~500 tokens per detailed response
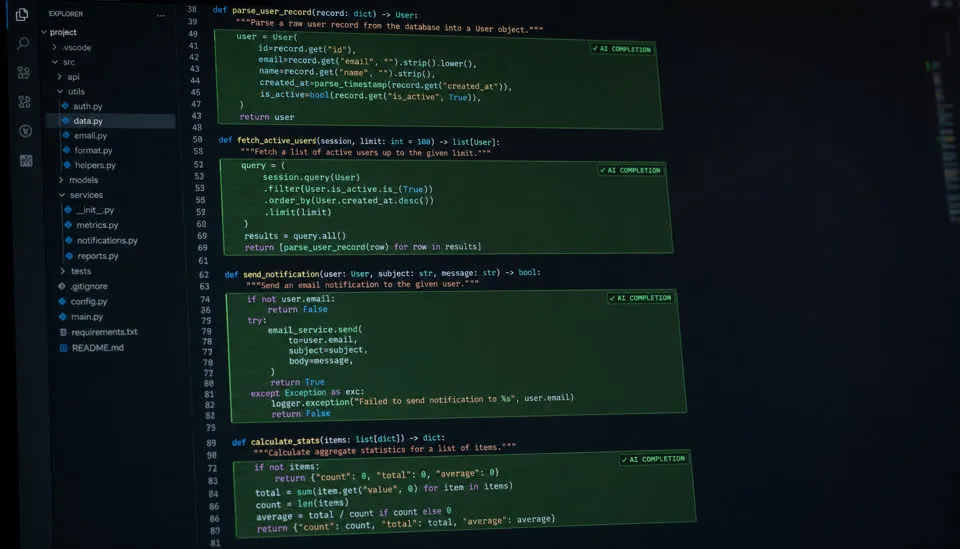
1 block = 1 completion
💻≈ 5,000 code completions
function implementations
A typical code completion — a function implementation, a refactor, a bug fix — runs about 200 tokens. A million output tokens is 5,000 of these.
basis: ~200 tokens per code completion
1 block = 1 article
📝≈ 500 blog posts
AI-written articles
A full blog post or report generated by AI averages about 2,000 tokens (~1,500 words). A million output tokens produces 500 complete articles.
basis: ~2,000 tokens per article
1 block = 10 emails
📧≈ 10,000 email drafts
AI-drafted email replies
A professional email reply generated by AI averages about 100 tokens (~75 words). A million output tokens drafts 10,000 emails — years of inbox assistance.
basis: ~100 tokens per email draft
1 block = 1 summary
📄≈ 1,000 document summaries
page-long summaries
A thorough document summary runs about 1,000 tokens (~750 words, a full page). A million output tokens produces 1,000 of these — an entire research library summarized.
basis: ~1,000 tokens per summary
1 block = 10 replies
🤖≈ 50,000 chatbot replies
short chatbot responses
A quick chatbot answer — a classification, a yes/no, a short extraction — averages about 20 tokens. A million output tokens is 50,000 of these, enough for a busy customer service bot.
basis: ~20 tokens per short reply